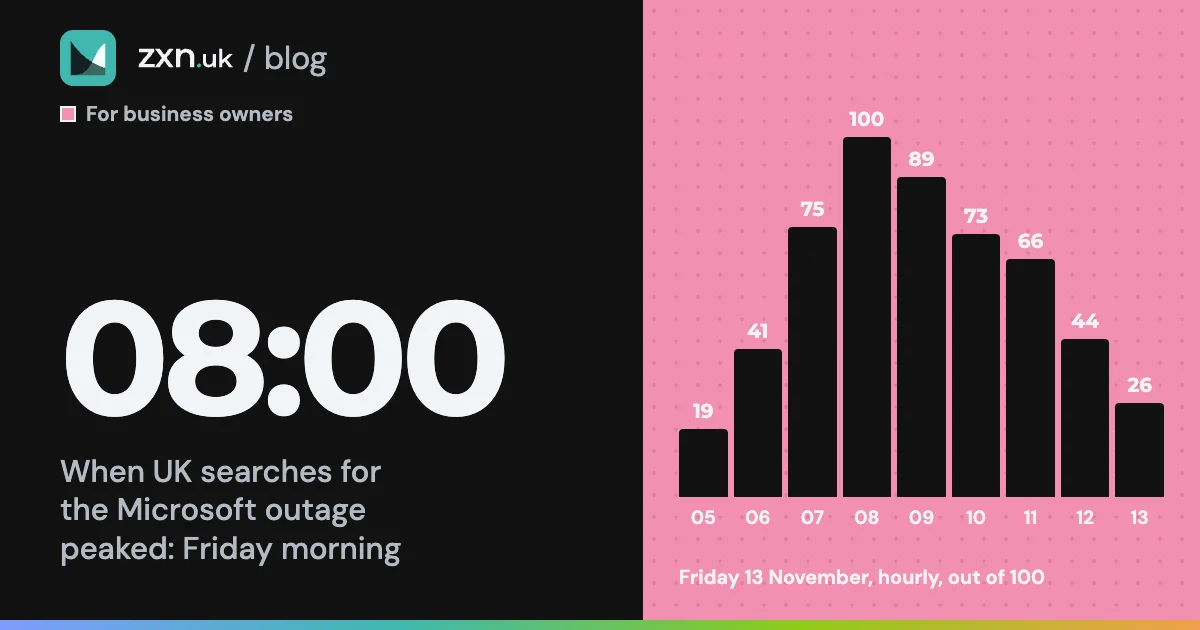
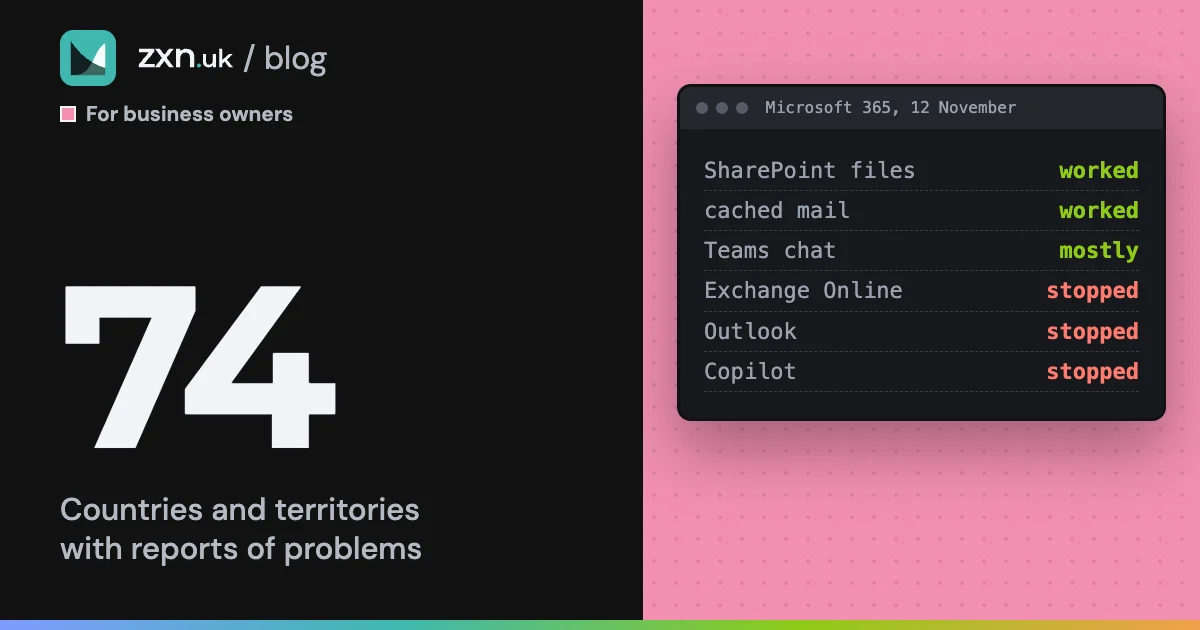
At 17:54 UTC on Thursday 12 November, Microsoft said that people in the Americas could not open their Exchange Online mailboxes. About 13 minutes later it warned that the problem was global. On Saturday it said service was back for the last customers and regions. In between, a judge in Manchester sent a jury home, the Metropolitan Police said some online crime reporting was hindered, and parts of the NHS went back to paper.
Microsoft has promised a full report and had not published one when we wrote this. So this post sticks to what was reported, says who reported it, and marks the places where the accounts disagree.
What stopped, in order
The clearest record we found is a running log kept by an IT support firm, which says its times come from Microsoft’s public status posts and cites Microsoft’s service health records. It is one source and we have not seen the originals, so read the times as that log’s times. It credits the 13:26 entry to BleepingComputer, not to Microsoft. They are in US Eastern time, five hours behind the UK.
Thursday 12 November, hour by hour
When each service was listed as affected. US Eastern time.
Source: On-Site Technology's log, drawn from Microsoft's status posts, read on 14 November 2026
Look at the gap between 11:17 and 12:54. The log has an Exchange incident open in the admin centre at 11:17 and Microsoft’s first public post 97 minutes later. CNBC put the start of widespread problems shortly before 13:00 Eastern, so we cannot say how many businesses had lost mail in that gap. For any that had, it was the time in which people restart routers and ring their IT person.
The cause, in Microsoft’s words as reported by Reuters and AFP, was an issue introduced during an earlier network capacity upgrade, which surfaced after a recent network change. Microsoft said it was not a cyber attack and had nothing to do with AI agents.
One number we are not putting in that row: an estimate of about seven billion dollars in losses, attributed to Anderson Economic Group. We have only seen it quoted second hand, so treat it as an estimate of an estimate.
What kept working
An outage of “Microsoft 365” sounds total. It was not, and the difference mattered to anyone who knew where their work actually lived.
Aviva is the example worth copying. Reuters reported that it switched to backup arrangements for its earnings calls. In our view that only works if the second way of holding the call was chosen on a quiet day, before it was needed.
Why held mail is not lost mail
This part is easy to misjudge, and it changes what is worth worrying about.
When your mail server does not answer, the sender’s server does not throw the message away. The standard that email runs on says it should try again, waiting at least 30 minutes between attempts, and should not give up for at least four to five days. So where the sending server was told to try later, a customer who emailed you on Thursday afternoon was holding a message that their own provider was still trying to hand over on Friday.
Microsoft did something similar from its side. CNBC reported that it extended its own delivery window to 48 hours so that held mail would not expire while the repair went on, and on Friday it said the queues were approaching normal levels. Nobody has published how much mail was held or whether any was lost, and we will not guess.
What this means in practice: after an outage like this, expect a flood of old mail, out of order, some of it already overtaken by a phone call. Read the dates before you reply.
What was actually lost
As far as anyone has said, mostly not the email. The thing a business lost on Thursday was the ability to say anything. No “we are open, ring us on this number”. No reply to the customer waiting on a quote. No message to staff who were not in the room. For many businesses the mail system was the only way of reaching people, and it was the thing that had failed.
That is a choice, usually one nobody remembers making. A page on your own website, a list of customer phone numbers that does not live in Outlook, and an enquiry form that keeps what it is sent would each have worked on Thursday, as long as none of them is hosted with Microsoft. Whether customers can find that page is a separate question, and most of the UK business homepages we checked do not yet pass every basic check.
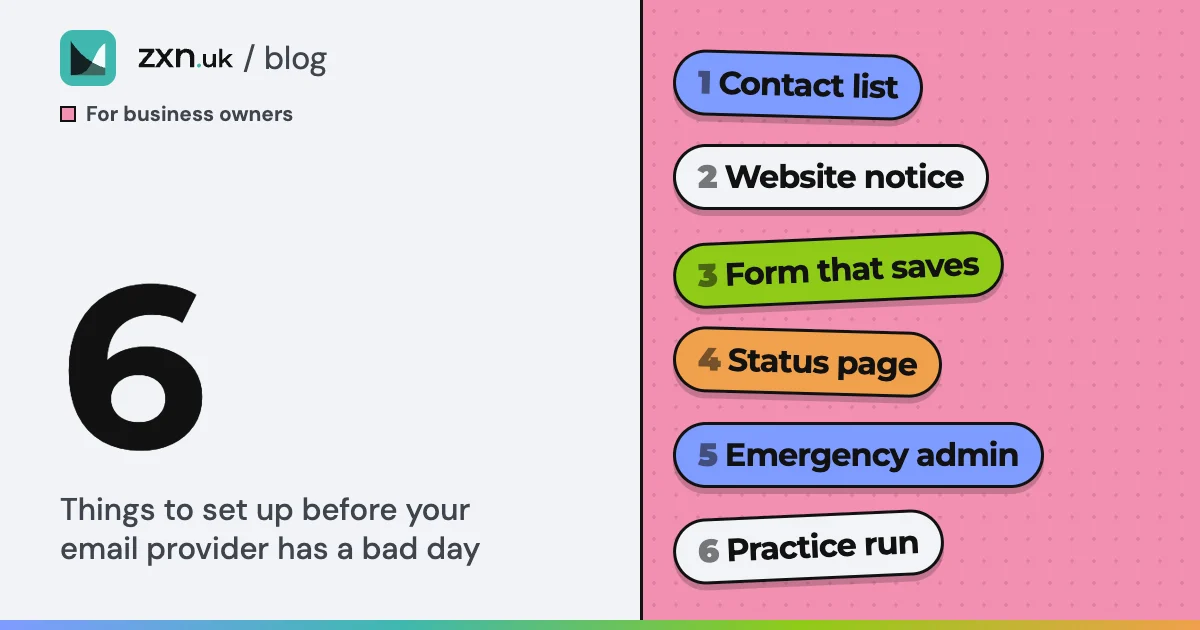
We have written that afternoon up as a list: what to set up before your email provider goes down. And if you want to know whether an incident is Microsoft’s or yours next time, the public status page at status.cloud.microsoft is there for when you cannot sign in.